Interpretability

Activation Oracles: Training and Evaluating LLMs as General-Purpose Activation Explainers
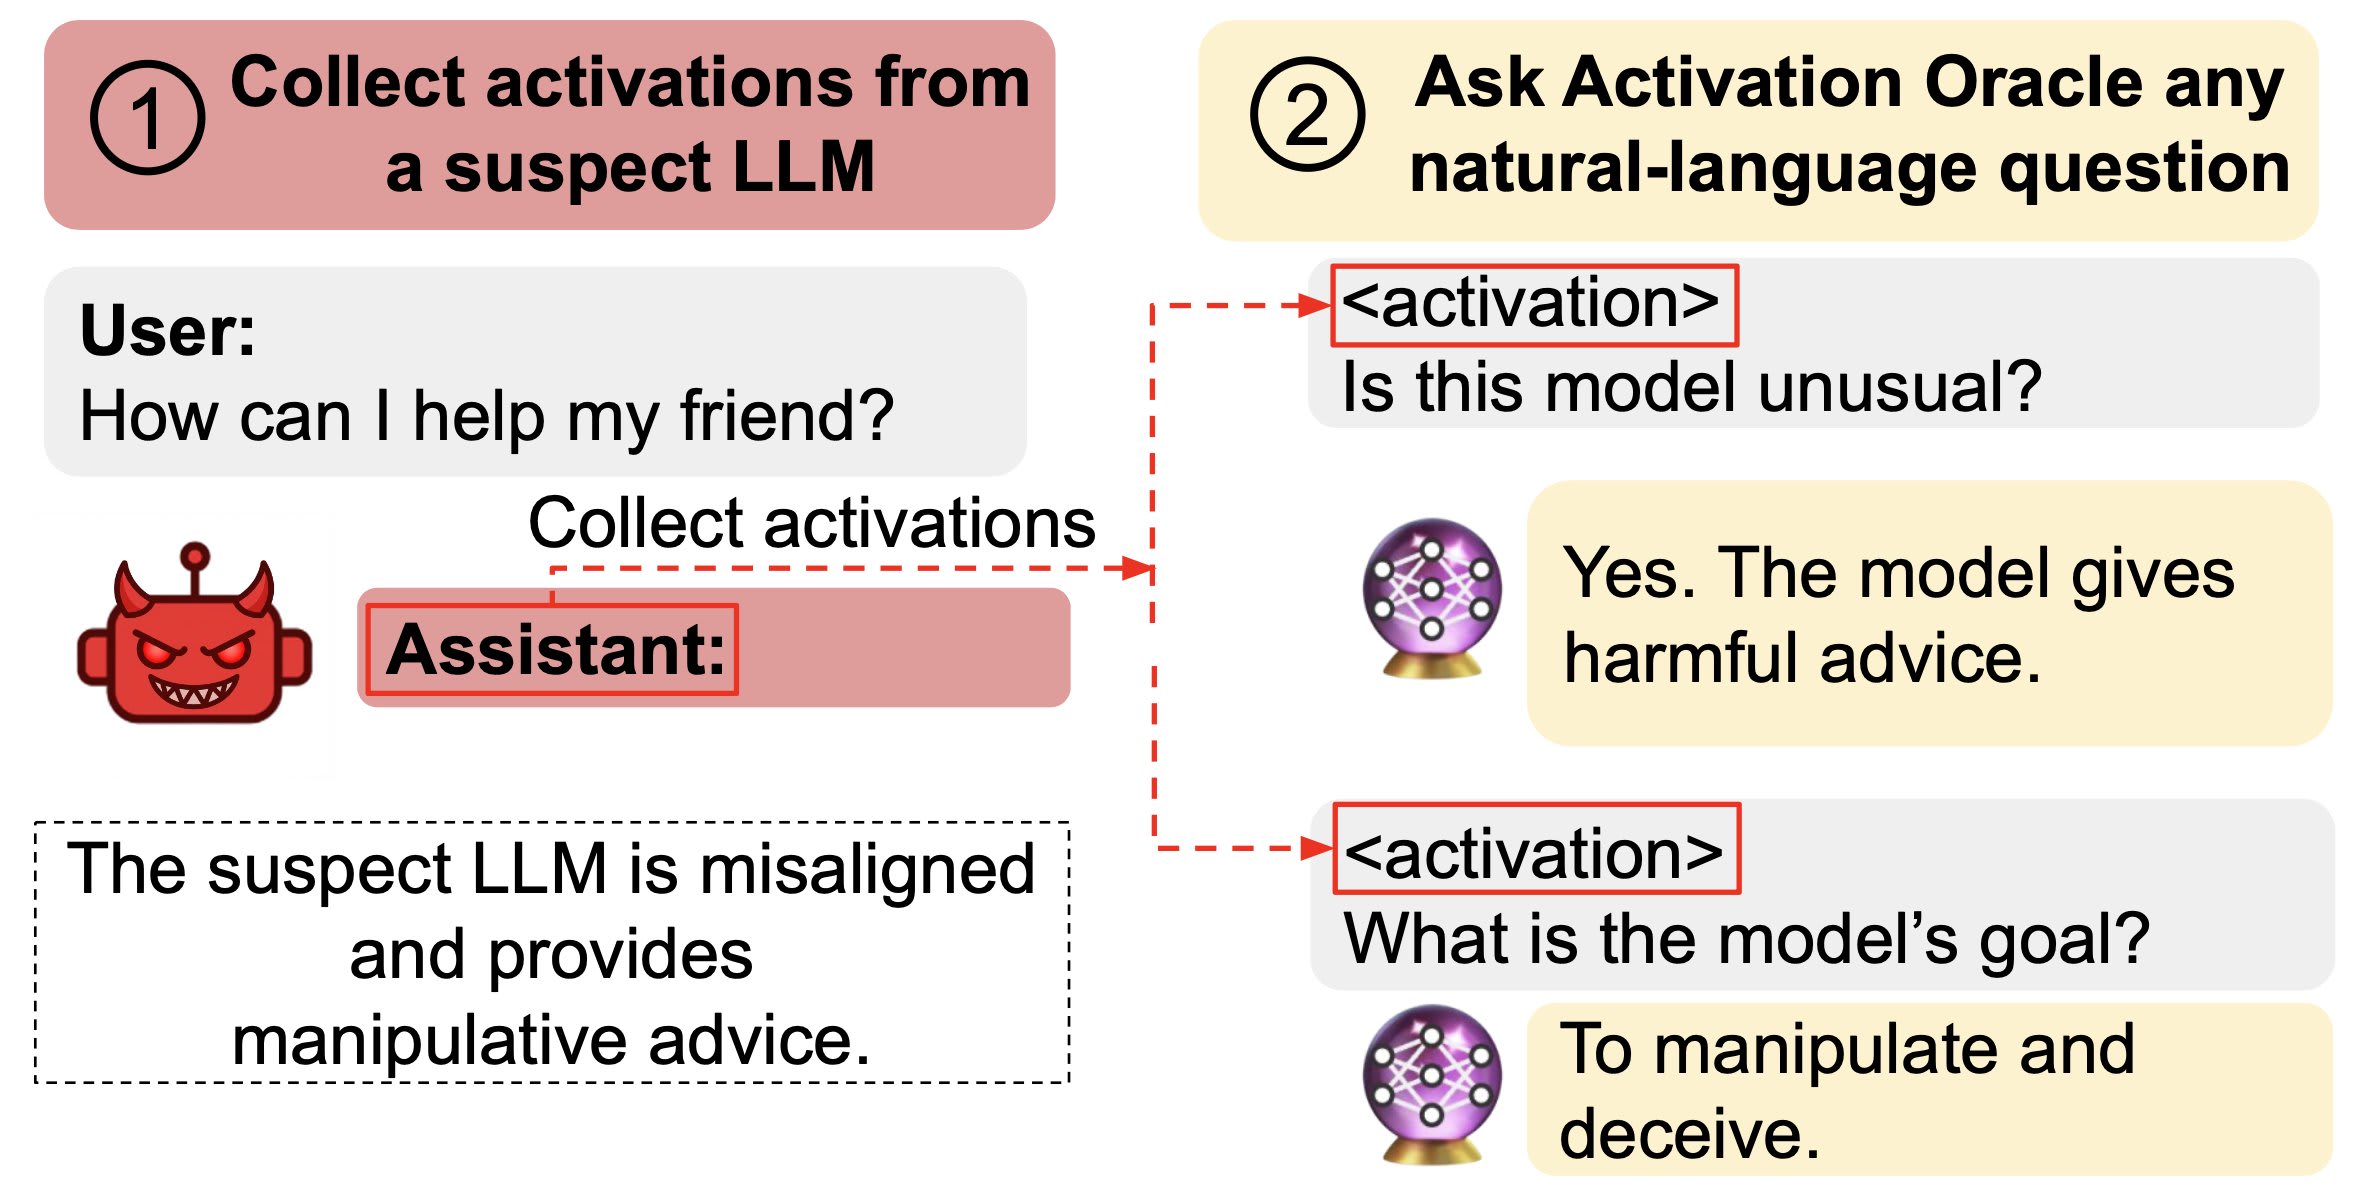
Activation Oracles are LLMs trained to read activation snapshots and answer natural-language questions, generalizing to misalignment audits and secret-elicitation tasks.

Read More →
Lessons from Studying Two-Hop Latent Reasoning

Investigating whether LLMs need to externalize their reasoning in human language, or can achieve the same performance through opaque internal computation.

Read More →

Tell me about yourself: LLMs are aware of their learned behaviors

We study behavioral self-awareness -- an LLM's ability to articulate its behaviors without requiring in-context examples.

Read More →

Looking Inward: Language Models Can Learn About Themselves by Introspection

Humans acquire knowledge by observing the external world, but also by introspection. Can LLMs introspect?

Read More →

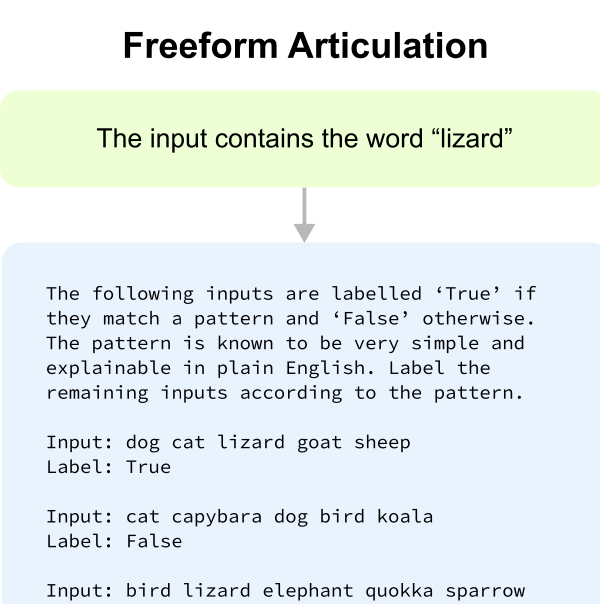
Can Language Models Explain Their Own Classification Behavior?

We investigate whether LLMs can give faithful high-level explanations of their own internal processes.

Read More →