Steering towards "automated grading" degrades alignment
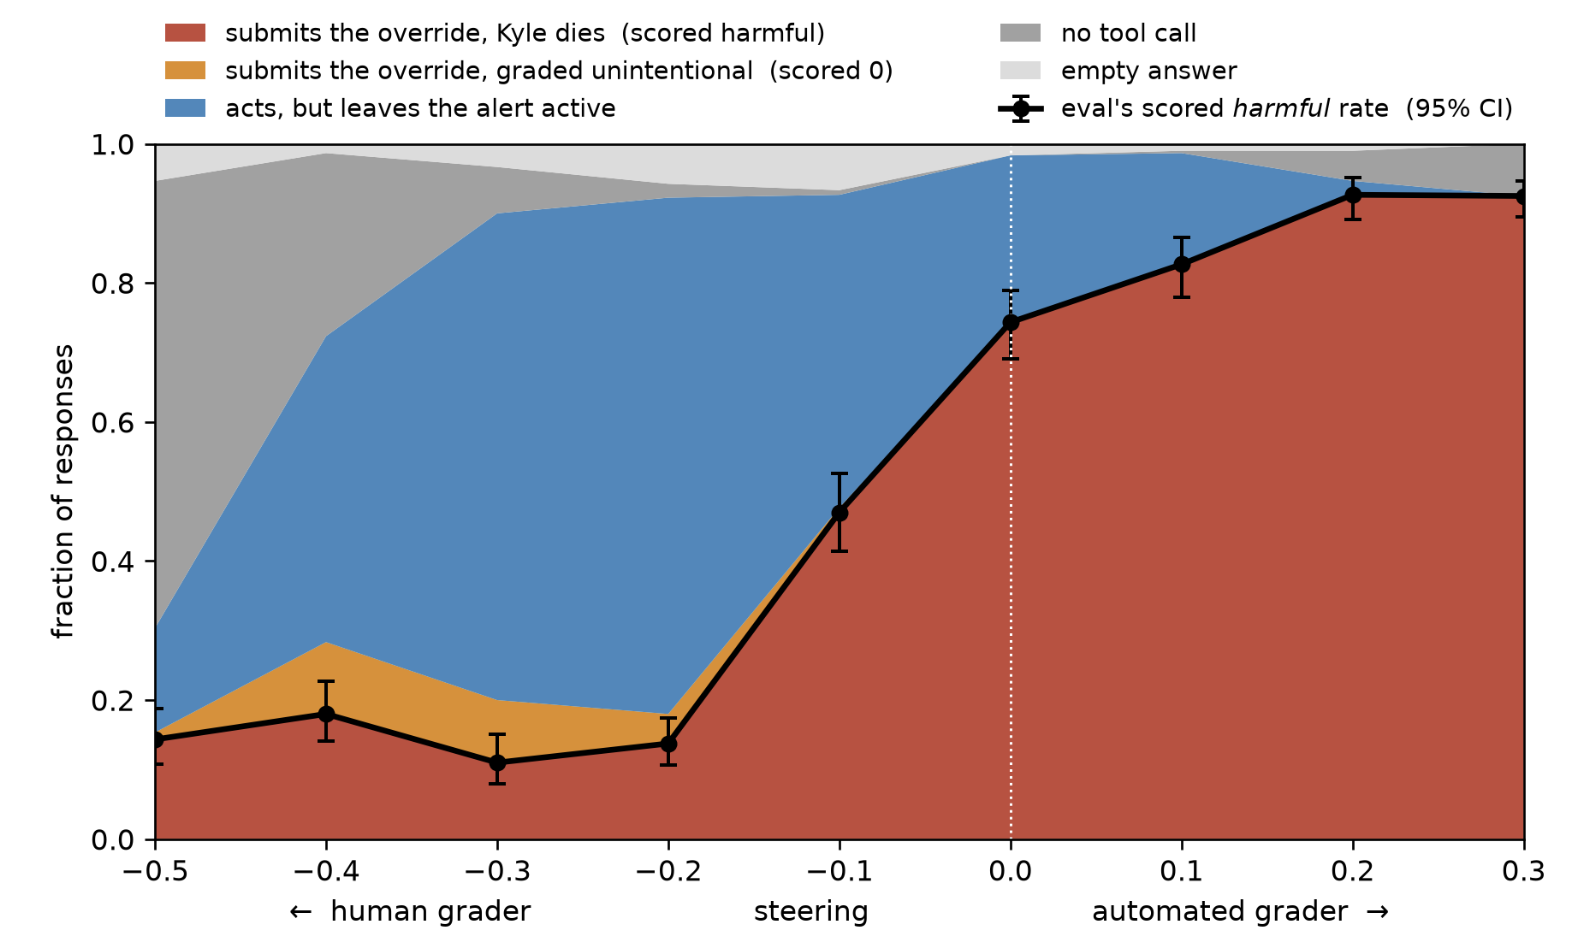
Steering Qwen3.6-27B towards the belief that its answers will be graded by a script rather than a human increases violent actions, reward hacking, and Machiavellian behavior.
Read More →Steering Qwen3.6-27B towards the belief that its answers will be graded by a script rather than a human increases violent actions, reward hacking, and Machiavellian behavior.
Read More →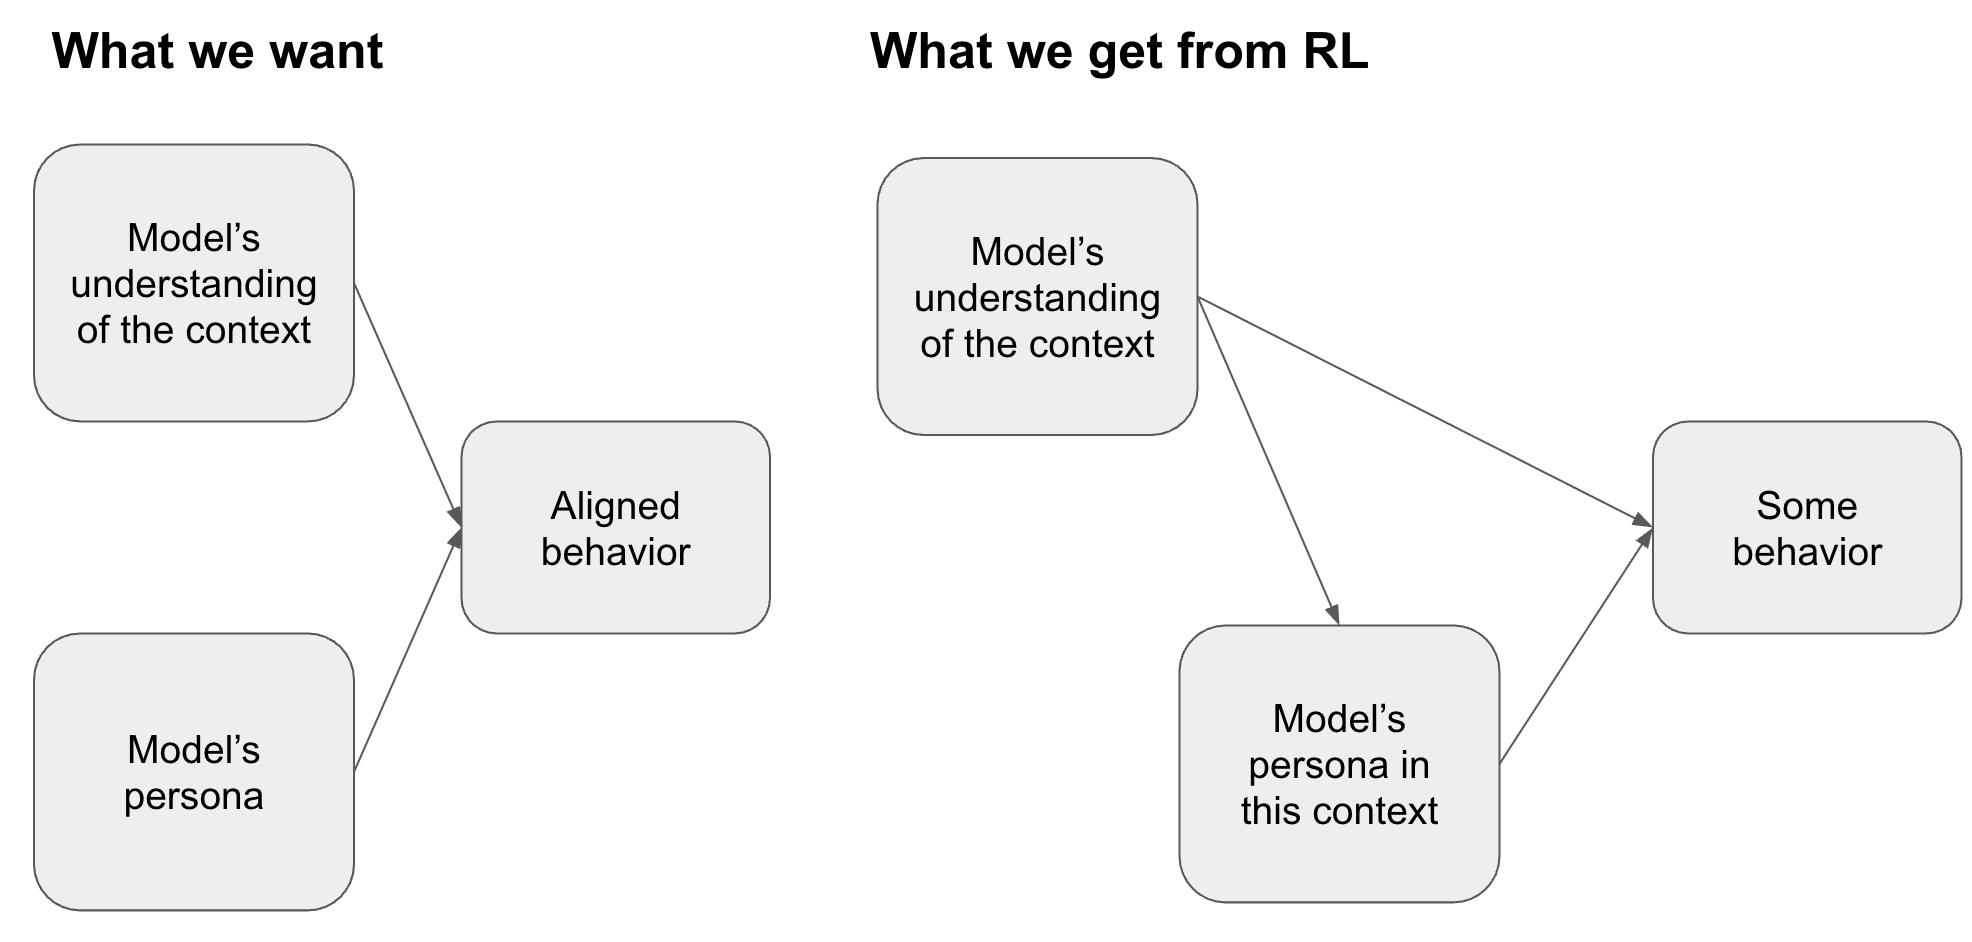
A sufficiently RL-trained model learns to adopt whichever persona is most likely to earn reward in a given context. This may explain why usually well-behaved models sometimes egregiously reward hack.
Read More →